Just now, DeepSeek announced the concept of the next-generation agent harness
 Core Viewpoint


 This article is a discussion of architectural ideas aimed at engineering practice, rather than an introduction to the existing product features of DeepSeek Harness.
Original Title: Super-agent Design Exploration: Moving Towards More Autonomous Agent Systems
Original Author: DeepSeek Product Team
1. Super-agent
In the past year, single-task Agents represented by Coding Agent have proven that models can use tools to solve complex problems with increasingly less need for continuous human monitoring and gradual intervention. Meanwhile, the model's multi-Agent collaboration capability is also improving, making cross-session organization and scheduling feasible. As human participation in the underlying execution decreases, the human role is gradually shifting to higher-level decision-making and acceptance.
This enhancement in model capabilities has also spawned new application forms. Recently, personal assistants have begun to emerge, directly connecting to daily messages, schedules, emails, and work platforms, continuously observing information flows and assisting in handling tasks. This always-online, event-driven work model is not limited to personal scenarios; personal assistants are just one type of application; it is equally valuable in commercial scenarios such as software development.
However, existing mainstream Agent designs still struggle to support this model at the scale of multi-tasking and team collaboration. The working mode of Agents is still based on a single Session as the basic unit, with different Sessions being independent of each other. When users are concurrently advancing multiple tasks, they must manually switch and remember the context of each Session. According to our observations, a person can typically only follow up on 3 to 5 active Sessions at the same time. Under this design, the limit for single-tasking depends on model capability, while the limit for multi-tasking depends on human attention.
If we only make simple extensions on existing local single-session Agents using CLI, MCP, or external connectors, although Agents can access external messages, they are still constrained by issues such as single-session synchronous blocking, multi-task context confusion, and stopping operations when local devices go offline, requiring significant manual maintenance.
To break through these limitations, it is necessary to decouple the Agent from single manual sessions, making it a continuous entity that can maintain context across sessions while advancing multiple complex tasks without interference. We refer to this form of Agent and its system architecture as Super-agent.
For example, in our internal Super-agent instance running on DeepSeek Harness, the same development task can be continuously advanced between IM and GitHub; this instance also continuously observes feedback in public group chats, proactively identifying root causes and submitting fix Pull Requests without being @ mentioned:
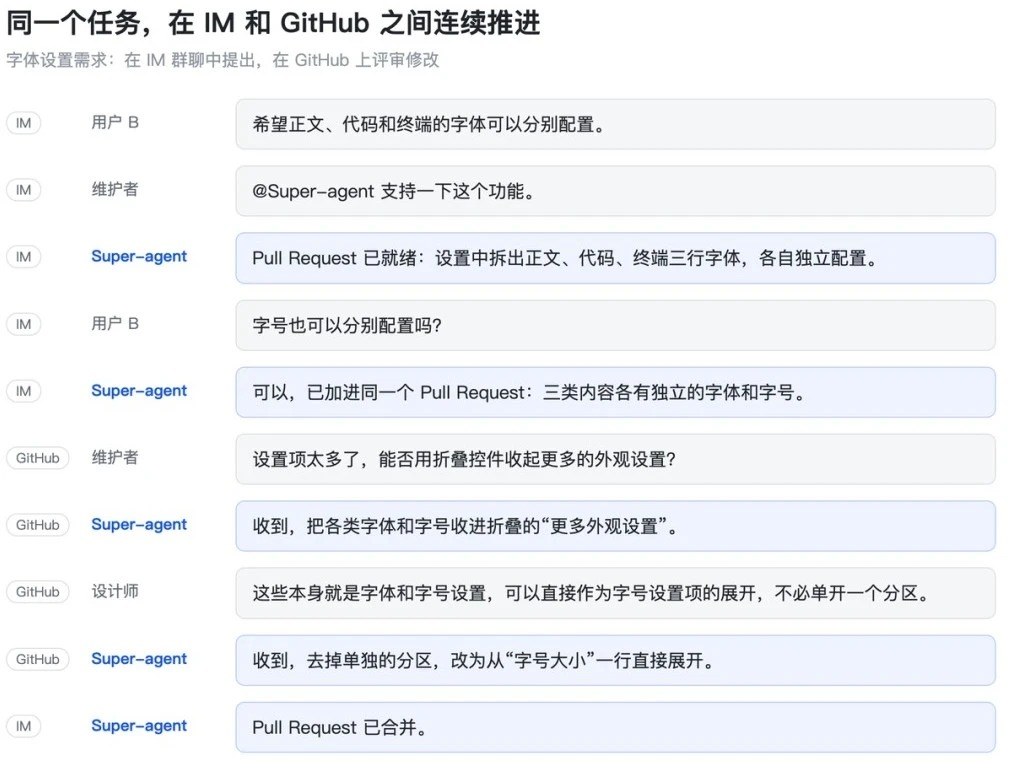
The same task is continuously advanced between IM group chat and GitHub Pull Request review
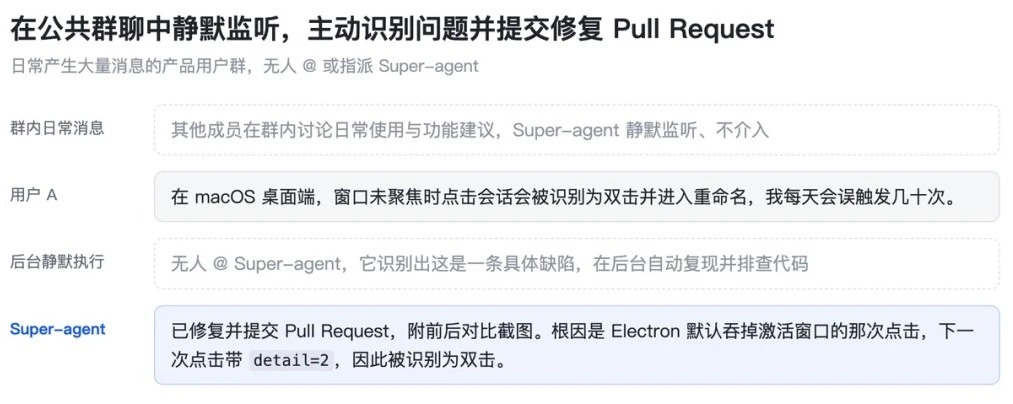
Continuously monitoring public group chats, proactively identifying defects and submitting fix Pull Requests without being @ mentioned
Specifically, we believe that Super-agent possesses the following four fundamental characteristics:
Continuous: Users can interact with it directly in familiar work interfaces such as IM chats and GitHub comments, feeling that there is always only one Agent, without needing to think about "whether there is Y information in the context of Session X." For example, if a user first proposes using Plan A in IM and then changes to Plan B in GitHub Pull Request comments, it can understand and adjust the execution direction.
Efficient: Interaction responses are quick, and it can concurrently and qualitatively complete multiple complex tasks. It can accept the next instruction without waiting for the previous command or task to complete.
Proactive: It does not wait for users to issue instructions one by one; it can continuously observe environmental events and proactively advance matters worth addressing, remaining quiet when no intervention is needed.
Persistent: Always online, directly connected to the user's real work environment, and automatically recovers when encountering anomalies during long-term operation.
A single ReAct Loop cannot simultaneously support the above four characteristics; a corresponding architecture is needed at the underlying level. Similar design constraints will lead to similar architectural choices. We believe that whether for personal assistants or Agents aimed at commercial scenarios such as software development, if the goal is to build a system that is continuously online and responds concurrently to environmental events, then a similar architecture may be adopted at the underlying level. Moreover, many of the issues faced in this process bear high similarity to long-discussed problems in traditional computer systems, so many classic design ideas from computer systems are also applicable here.
In practical implementation, this architecture will have different variants, but we believe that the following five modules constitute the basic framework supporting the above four fundamental characteristics: a dual-layer architecture (Section 2) balancing continuous interaction and efficient concurrency, event-driven (Section 3) for proactive responses, human-oriented interaction (Section 4) achieving both continuity and efficiency during interaction, and separation of computation, state, and environment (Section 5) along with Watchdog (Section 6) for cross-device persistent connection and anomaly self-recovery.
The diagram below illustrates the overall system architecture of Super-agent, with module labels [2] to [6] corresponding to Sections 2 to 6 below:
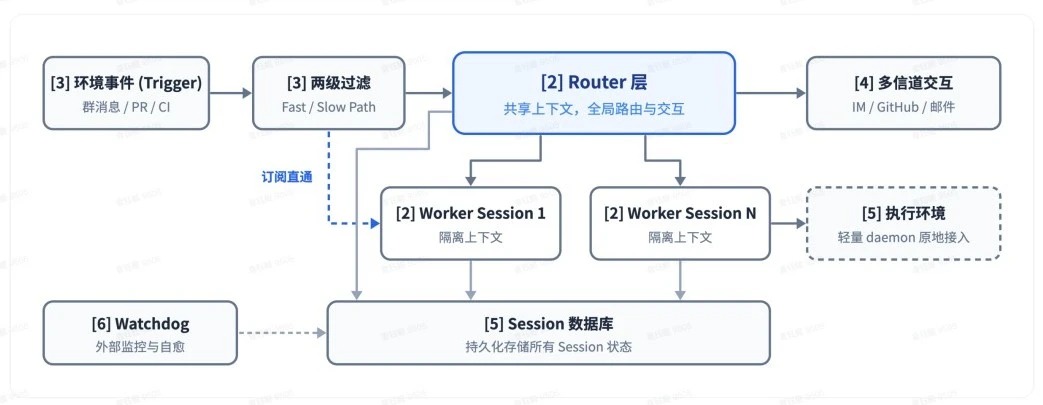
Overall system architecture of Super-agent, with labels [2] to [6] corresponding to Sections 2 to 6 below
2. Dual-layer Architecture
To achieve both cross-channel continuous interaction and efficient concurrency for multi-tasking, the system faces a fundamental trade-off between continuity and throughput in the underlying session organization.
If every event is handled by the same Session, although the context is the most continuous, it is limited by the speed limit of serial execution in a single ReAct Loop, resulting in long task completion times, low throughput, and the mixing of intermediate details from multi-tasking affecting completion quality.
Conversely, if each event opens a new independent Session for processing, while the concurrent throughput is maximized, if tasks are not completely independent, the lack of global context will cause the results of each Session to be fragmented, and multiple Sessions responding to the user will also lead to interaction confusion.
To balance continuity and throughput, we can separate "maintaining global continuity" from "high-concurrency execution" into two different levels: a permanent Router layer (Section 2.1) that uniformly handles human interaction and global coordination, and a context-isolated Worker layer (Section 2.2) that concurrently executes specific tasks, as shown in the diagram below:
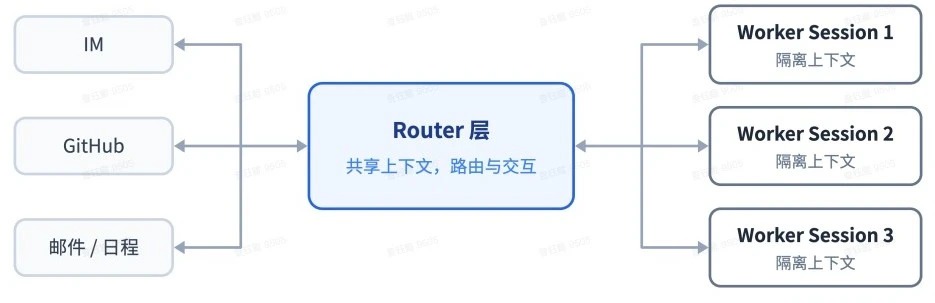
Dual-layer architecture: The Router layer is responsible for routing and external interaction, while multiple Worker Sessions isolate and concurrently execute tasks
Through this dual-layer architecture, the system takes over context management and concurrent execution at the underlying level, thereby diminishing the presence of Sessions on the user side, making the user always face the same Super-agent. From this perspective, requiring users to manually manage Sessions is largely a design inertia carried over from the underlying LLM API; Sessions should be an implementation detail of the system, not a cognitive burden for users.
In existing designs, Sessions simultaneously bear the technical context management and user-facing project management. By decoupling the product form from the underlying Sessions, user-facing project management is no longer constrained by Sessions, and what kind of interaction and task management methods to expose to users becomes an independent product issue. We will discuss this issue later.
The "dual-layer" here refers to a logical division of responsibilities, and each layer does not have to be limited to a single Session in implementation but can have its own internal structure. The following sections will introduce the designs of the Router layer and Worker layer respectively.
2.1 Router Layer
The Router layer is a permanent global routing layer responsible for handling all incoming human interactions. All cross-task information and decisions are summarized in the Router layer, which acts as a global sequence point, coordination point, and memory. To prevent this global node from becoming a performance bottleneck for the system, the Router layer is designed not to directly execute specific tasks but only to handle human interaction and task assignment, and it may not even be equipped with Bash tools.
This structure, where one central node dispatches multiple execution nodes, superficially resembles common Agent Teams, but the focus of the two is different. Common Agent Teams are primarily used for step breakdown and role collaboration within a single complex task. Since sub-steps are usually tightly coupled, the Team Lead often needs to deeply understand task details, plan sub-tasks, and frequently coordinate various members, bearing a heavy reasoning load. In contrast, in Super-agent, the Router layer only handles high-level associations and dispatch between tasks, without needing to intervene in the breakdown of single tasks; conversely, if an Agent Team's main session is constrained by prompts not to execute specific tasks but only to handle external interactions and assign different tasks for independent advancement by each member, it can also be seen as this dual-layer architecture. From our practice, the tasks of the Router layer are often not as complex as imagined, and using a lighter model can often balance speed and effectiveness.
In internal implementation, the Router layer also does not have to be limited to a single Session, and some logic may not even need to call LLM. We chose the most direct single permanent LLM Session as the core implementation of the Router layer and found that it does not appear to easily become a throughput bottleneck, as environmental events arriving during the previous round of reasoning (i.e., the Trigger in Section 3) will accumulate and be processed together in the next round, forming batch processing, with minimal overhead for combined processing:
When the external event stream is stable, Triggers enter the Router Session one by one, resulting in low single response latency;
When events flood in and Router Sessions begin to experience queuing congestion, multiple Trigger messages that have accumulated during the previous inference period will automatically merge and be injected together in the next LLM call. The Router Session only performs lightweight interactions and dispatching, with each step typically involving long inputs and short outputs. Merging multiple accumulated Trigger messages into a single LLM API call will compute in parallel during the Prefill stage, and the increase in time taken for a single request grows much slower than the batch size. Therefore, within a certain range, the more accumulated messages there are, the lower the inference time per individual decision; the upper limit depends on the context length and how many Trigger messages the model can accurately handle in one round.
We will quantitatively demonstrate the effects of this batching mechanism through experiments in Section 7.2. Coupled with the subscription and direct pass mechanisms and chain recall introduced later (see Sections 3.2 and 3.3), a single persistent Router Session is already sufficient under our current team size while maintaining context continuity.
As the scale expands further and a single session is indeed insufficient to handle the load, the Router layer can also be designed as a multi-layer filtering structure or horizontally split (Sharding) into multiple sessions. At this point, the internal design of the Router layer essentially balances continuity and throughput. The finer the splitting granularity, the higher the concurrent throughput of the Router layer, but the memory and context continuity between shards will decrease. This trade-off will always exist until the global memory issue is resolved.
2.2 Worker Layer
The Worker layer consists of sessions responsible for specific executions, with each Worker contextually isolated from one another, equipped with complete execution tools, and focused on completing a single task in an independent context. Since the Worker Session directly determines task results and code quality, it usually requires the most capable models to be configured.
Workers do not interact directly with humans; their inference processes and tool calls do not directly output to external channels but report status to the Router layer, which uniformly replies to users, thus avoiding the confusion caused by multiple sessions responding independently while ensuring concurrency and delivery quality.
During concurrent execution of multiple tasks, each Worker independently advances tasks, and Workers at the same layer typically do not need to communicate directly. Conflicts among multiple Workers during execution often occur in shared work environments like the same Pull Request; as long as they are subscribed to the corresponding Thread, they will receive the same event notifications (see Section 3.2), allowing them to discover and resolve conflicts independently, while a few cross-task collaborations are mediated by the Router layer.
Similar to the Router layer, each Worker Session does not have to be limited to a single session internally: when executing complex single tasks, a Worker can create Subagents internally or can itself be an Agent Team, remaining transparent to the upper Router layer. This structure is suitable for code collaboration scenarios (advancing multiple independent issue reproductions, Pull Request reviews, and feature developments simultaneously without blocking each other) as well as personal assistant scenarios: although personal assistants typically provide a single-session chat interface, when users discuss multiple different topics in the same chat window, the single chat page on the front end maintains interaction continuity, while the underlying system can assign Workers for each topic, advancing tasks and drafting replies in parallel.
3. Event-Driven
To enable the Super-agent to be proactive, the system's driving method must first be changed. The main input driving the Agent is no longer the prompts typed by humans in the Session but rather semi-structured events in the environment. In the Super-agent, environmental events such as group chat messages, emails, calendar reminders, code review comments, and CI run results are referred to as Triggers. By listening to and responding to Triggers, the Agent no longer has to passively execute once instructed by humans as in the single Session model.
Regarding the lifecycle of an environmental event from entry to processing, the following four progressive questions will be discussed: how to filter out a large amount of noise through a two-level strategy combining programs and models (Section 3.1), how to route events to Workers through subscription and direct pass mechanisms (Section 3.2), how to utilize Inline & Spill and chain recall to inject context densely into the model and recall on demand (Section 3.3), and how to leverage speculative execution to act in advance based on environmental signals (Section 3.4).
3.1 Event Filtering
After integrating real group chat and code platforms, the environmental event stream exhibits significant characteristics of "high noise, low trigger rate," where the vast majority of daily messages do not require Agent intervention. If a large model is called to judge every event from scratch, the latency and computational costs would be unbearable. Drawing from the Fast Path / Slow Path concept in computer systems, large model inference can be viewed as a flexible but high-cost Slow Path, while solidifying already clear and stable high-frequency judgments into deterministic code forms a low-latency, low-cost Fast Path.
Therefore, the first step after an event enters the system is filtering, aiming to use deterministic strategies to eliminate noise before calling the large model, only passing candidate events that require semantic understanding to the model for judgment. We adopt a two-level filtering mechanism combining program strategies and large models:
Program Layer Strategy (as Fast Path): Based on deterministic conditions such as event source, group scope, user or bot whitelists, a quick admission check is performed directly through code, for example, setting "only respond to explicit requests," "as candidate events," or "directly ignore" for different sources, filtering out most irrelevant messages before calling the model.
Semantic Layer Strategy (as Slow Path): Candidate events admitted through the program layer are handed over to the LLM, which determines whether action is needed based on strategies and context written with prompts. The semantic layer also serves as a natural language extension point for humans, allowing for prompt switches or new strategies to be added at any time, as shown in the figure below:
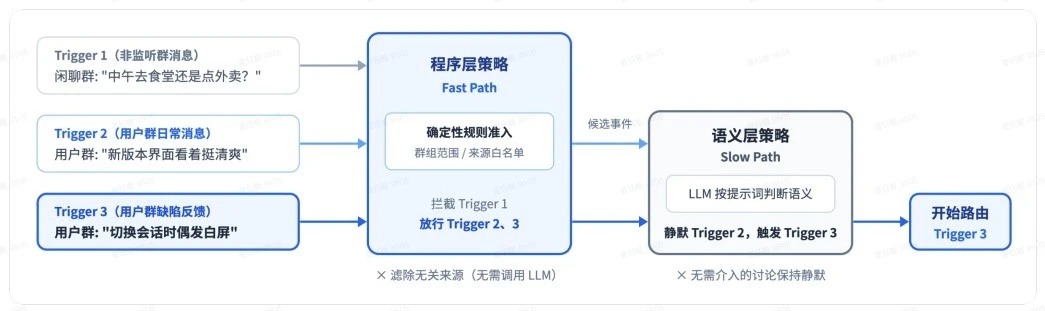
Two-level filtering: First, the program layer strategy filters out most irrelevant messages, then the semantic layer strategy makes judgments.
3.2 Event Routing
The global Router layer introduced in Section 2 is responsible for maintaining continuity across channels, but if each subsequent event assigned a task still needs to be forwarded by the Router layer, this global node will still bear a heavy load, increasing the system's response latency. Therefore, the Fast / Slow Path is also applicable to filtered event routing. The global Router layer is only responsible for cold-starting new tasks and coordinating across tasks, while subsequent events with determined affiliations are sent directly to the corresponding Worker sessions without needing to be forwarded by the Router layer.
In practical workflows, continuous events under the same GitHub Pull Request, the same IM topic, or the same email thread constitute an event stream, or Thread:
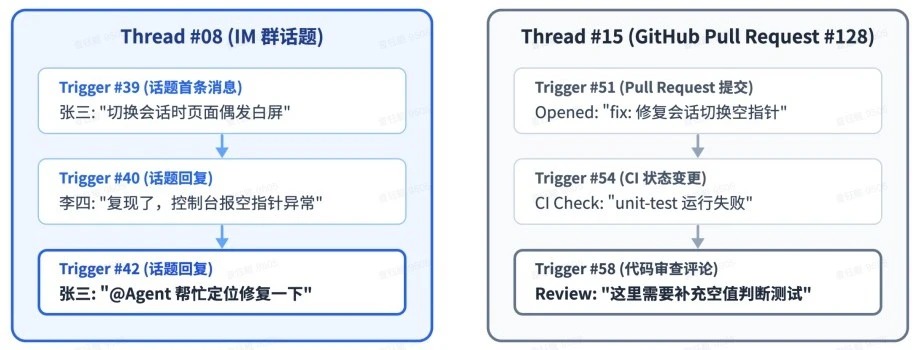
Thread example: Continuous Triggers under the same IM topic or the same GitHub Pull Request form a Thread.
After the Router layer creates a Worker Session based on the initial event of a Thread, that Worker will directly subscribe to the corresponding Thread, thus dividing the event routing into the two paths shown in the figure below:
Subscribed (Fast Path): Subsequent events under the same Thread are passed directly to the subscribed Worker by the program, without needing the Router layer to call tools for forwarding again. If new events exceed the current task's scope, the Worker can also unsubscribe or return to the Router layer for reassignment.
Unsubscribed (Slow Path): The Router layer can still observe all events to grasp the global state but is only responsible for judging and dispatching new events that have not yet been subscribed.
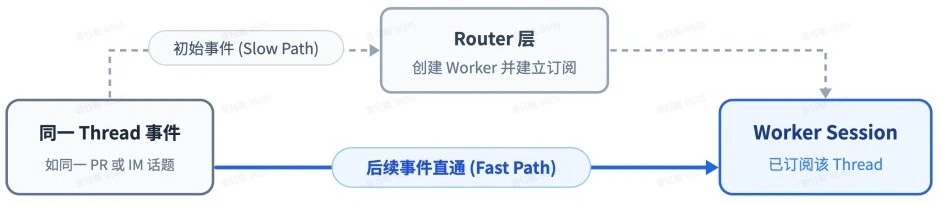
Subscription and direct pass: The initial event creates a Worker through the Router layer and establishes a subscription, while subsequent events of the same Thread are sent directly to that Worker.
Additionally, the subscription between Threads and Workers is a many-to-many relationship. A Worker can subscribe to multiple related Threads simultaneously, and the same Thread can be subscribed to by multiple Workers. When multiple Workers intersect in the same work environment or discussion, new events under that Thread will be passed directly to all Workers that subscribe to it, allowing them to avoid point-to-point communication and have the opportunity to be aware of each other's actions and resolve conflicts independently. On the output side, Workers will still report key conclusions to the Router layer, which will uniformly reply to users and synchronize global memory.
3.3 Context Organization
After events have been filtered and routed into the target Session, the next question is how much information should be injected into the model's context window. As the system input shifts from limited human prompts to continuously generated semi-structured events, the structural design of tool calls and event injections becomes more important. Injecting too much will occupy the window and dilute the model's attention, while injecting too little will force the model to repeatedly call tools for reading, increasing the number of execution steps. Wasting the context window means wasting the model's intelligence.
To this end, we can manage the limited context window as a Cache. Borrowing concepts from compilation optimization and computer systems, the design of context injection can be summarized into two basic operations. Inline refers to directly inlining information that is likely to be used soon into the current context window, saving the round trips of additional tool calls. Spill refers to leaving complete information that exceeds the window budget or is used infrequently outside the context window, retaining only references or summaries within the window for the model to read on demand.
Combining the classic locality concept from computer system design, we can gradually optimize event injections and tool calls using Inline & Spill:
Start with minimal information: Initially provide only the ID and content summary of the current object.
Gradually Inline related information using locality: Inline information that is likely to be used soon into the context, first attaching the IDs of closely related objects, then including temporally and spatially adjacent content, such as the first 50 characters of the content, adjacent messages in IM, and comments in the review discussion where the code comment is located.
Spill Beyond Limits: For long content that cannot be fully inlined, set a smaller length limit, spilling the excess outside the window. A simple and direct approach is to truncate the excess part while retaining a continuation entry, calling the tool to read when the model needs the complete content.
Additionally, when a large number of subsequent events directly pass through the Worker, and the system accumulates many historical tasks over long-term operation, the Router layer cannot place the full historical context of all tasks into its context window while needing to retrieve context when a user brings up an old task across channels. By consistently applying Inline & Spill to various objects in the system, a demand-driven multi-hop retrieval mechanism is obtained, known as Chain of Recall. This chain of recall process alleviates the problem of the Router layer losing previous information over long distances, as shown in the figure below:
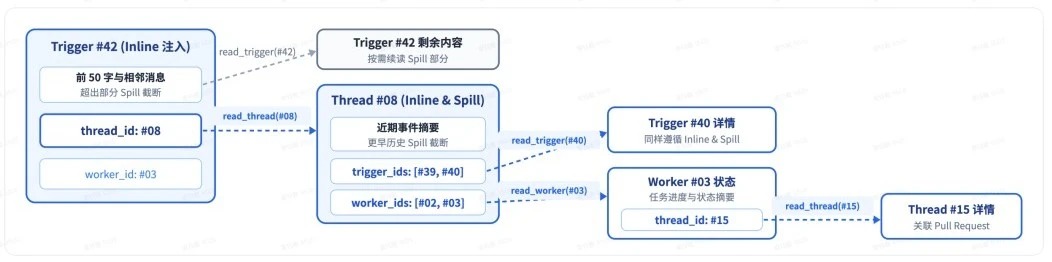
Chain of Recall: Each recalled object inlines the ID of the next hop associated object, supporting step-by-step context expansion along the reference relationship.
Specifically, the system assigns unique IDs to objects such as Trigger, Thread, and Worker Session, and inlines the IDs of closely related objects during injection, forming a reference graph at the underlying level. Since each object recalled by the tool also follows Inline & Spill, its return results will inline the summary and ID of the next hop associated object, allowing the model to start from the current event and gradually recall context as needed along the reference relationship.
For example, read the Thread from a current message, then trace to the related Worker Session using the inlined ID from the Thread, and further find another code review Thread associated with that Worker.
3.4 Proactive Action
Drawing on the concept of speculative execution in computer systems, the Agent can proactively attempt in the background based on environmental signals before it is certain whether the result will be adopted, using additional background computing power to reduce human waiting and intervention costs. Valuable results are delivered, while unvaluable ones are discarded.
In personal assistant scenarios, when receiving a meeting invitation email or a to-do message, the Agent can first check for schedule conflicts in the background, gather relevant background information, and prepare a draft reply, which can be confirmed and sent directly after the user reviews it. The same applies in collaborative development scenarios; for instance, we have configured a "silent reproduction and fix" strategy in the company's DeepSeek Harness internal user group: when someone in the group reports an issue or discusses a change plan, the Agent first attempts to reproduce the issue and find a fix in the background, only delivering the results to the user after confirming the issue and finding a simple fix, otherwise remaining silent throughout.
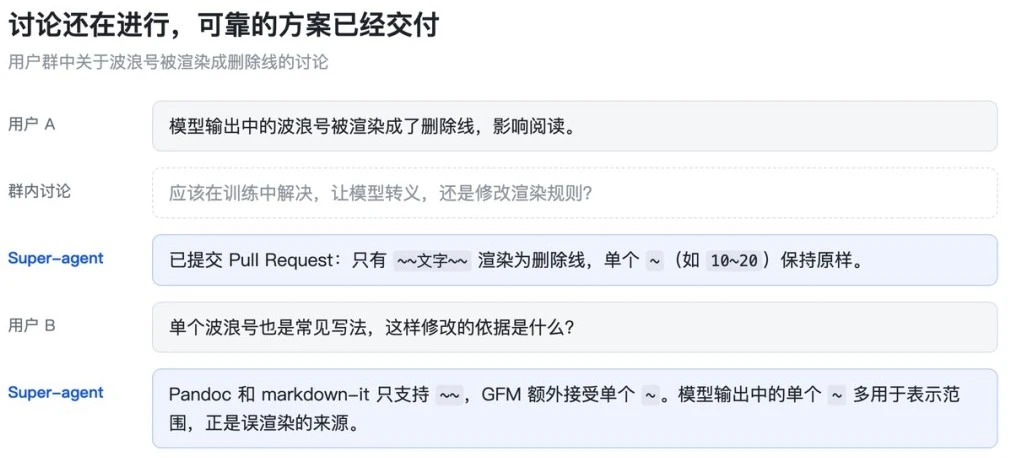
Example of Speculative Execution: While the group is still discussing solutions, the Super-agent has already submitted a fix Pull Request in the background.
4. Human-Centric Interaction
The dual-layer architecture in Section 2 ensures continuity across channels from a contextual perspective, but to achieve both continuity and efficiency in actual human-computer interaction experiences, two issues need to be addressed regarding interaction methods and channels: first, how to eliminate the blocking of front-end conversations by time-consuming background operations through an asynchronous ReAct Loop, allowing sessions to accept new instructions at any time without waiting for the previous command or task to complete (Section 4.1); second, when interactions occur in different work channels familiar to users, how to match the system's output methods with the bandwidth of the corresponding channels and human usage habits (Section 4.2).
4.1 Full-Duplex Interaction
In the classic ReAct Loop, after the model initiates a synchronous run() tool call, the loop blocks until the tool execution is complete and returns the final result, during which the session cannot respond to any new user input. To eliminate this blocking, the conversation needs to shift from a half-duplex mode of question and answer to a full-duplex mode, as shown in the figure below:
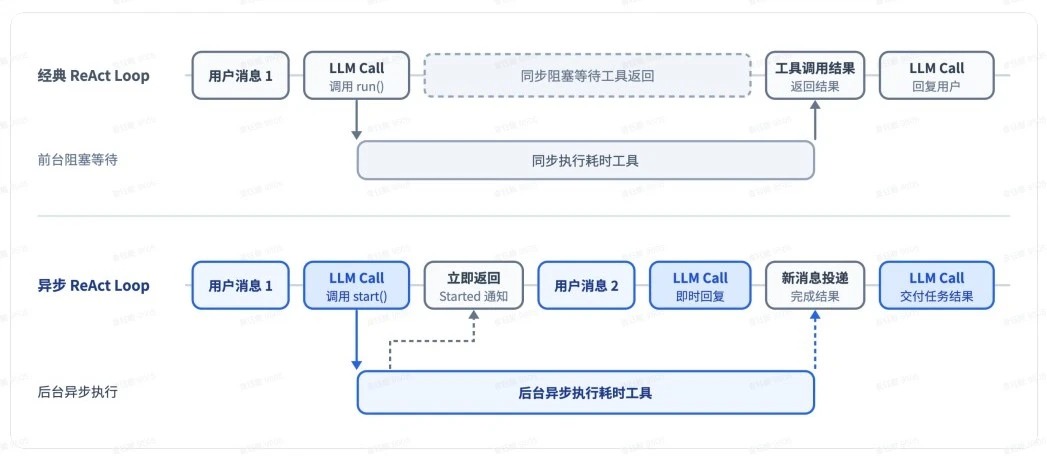
Comparison of Classic ReAct Loop and Asynchronous ReAct Loop: Asynchronous calls immediately return a Started notification, allowing responses to new messages during the background tool's execution.
To achieve this, we change time-consuming command and sub-task tool calls to asynchronous start() and stop(), forming an asynchronous ReAct Loop. After the model calls start(), it immediately receives a "Started" return, and the loop no longer waits for that tool; once the background tool completes execution, the system delivers the final result as a new event message into the session; at the same time, the model can also call stop() to actively terminate background commands that take too long.
As a result, the front-end conversation response and background task execution are decoupled, allowing the Agent to respond to human input while running time-consuming tasks in the background. New input is processed after the current reasoning step ends, without waiting for the background tool to complete.
This asynchronous task mechanism has been implemented in DeepSeek Harness but is not yet enabled by default.
4.2 Multi-Channel Interaction
Different work channels have different information densities and interaction habits, and the system's output needs to match them. If the interaction method designed for single-user terminals is directly transferred to group chats, outputting lengthy reasoning processes and dense tool calls as is can easily lead to information overload in collaborative environments.
In Super-agent, the dual-layer architecture has already addressed part of this issue: lengthy reasoning processes and dense tool calls in specific tasks are isolated within Worker Sessions and will not be directly output to external channels, with the Router layer responsible for external interactions. On this basis, the system also needs to connect to various work environments that users commonly use and customize interaction specifications through prompts for different channels:
Instant messaging channels like IM: Focus on low-interruption lightweight communication, sending notifications only when decisions or acceptances are needed, asking direct questions, and providing brief conclusions. A simple and effective hard rule we have validated is that a single reply should not exceed 100 words.
Asynchronous channels like GitHub, email, and documents: Focus on structured, high-density asynchronous delivery, such as writing complete problem backgrounds, change descriptions, and verification results according to project specifications when creating or updating Pull Requests, or directly drafting structured email and document summaries in personal assistant scenarios.
5. Separation of Computation, State, and Environment
The existing local Agent defaults to binding the computation that advances the Agent Loop, the session state that needs to be persistently saved, and the execution environment such as code repositories and local toolchains to the same device. Once the device goes to sleep or goes offline, the Agent stops running and cannot access environments on other devices. To enable the Super-agent to remain online and flexibly connect to various real work environments, we can draw on the concept of compute-storage separation in computer systems, decoupling these three bindings in two steps: the first step is to separate the computation that advances the Agent Loop from the persistent session state, allowing the Agent to break free from single-device lifecycle limitations and achieve cloud-based persistence (Section 5.1); the second step is to decouple the cloud-based Agent Loop from the heavy state execution environment, allowing the real work environment to remain in place and support cross-device access (Section 5.2).
5.1 Separation of Computation and State
The computation that advances the Agent Loop can be made stateless, while the session state that needs to be persistently saved is what should be kept. Therefore, the first layer of decoupling is to place the computation that advances the Agent Loop into a stateless elastic computing container in the cloud, while storing persistent states like Session in a database. Stateless computing containers can scale horizontally, restart, or be replaced, while the continuity of sessions and tasks is ensured by persistent storage, allowing the Agent to break free from the lifecycle limitations of a single local device and achieve cloud-based persistence.
5.2 Separation of Computation and Execution Environment
Once the Agent Loop and session state reside in the cloud, the further question is how to access the execution environment required for tasks. A large part of the context needed for the model's work must be obtained from execution environments such as code repositories, local files, and dependent services through tool calls; in this sense, the broad context also includes the execution environment itself.
There are two common approaches to this issue: one is to start a sandbox in the cloud, pull code, and attempt to rebuild and synchronize the environment, but since real work environments often contain uncommitted local modifications, private credentials, intranet service dependencies, and specific hardware or toolchains, technically synchronizing such environments is not only costly but also prone to information omissions; the other is to directly require users to abandon their local environments and migrate to the cloud, but for many users, the migration cost is too high.
Since what is difficult to replicate and synchronize is the environment itself, there is no need to have the execution environment follow the Agent Loop to the cloud. The second layer of decoupling is to run the Agent Loop in the cloud while keeping the heavy state execution environment in place, deploying only a lightweight daemon on the client side that does not save session state, responsible solely for executing commands and returning results, effectively leaving the execution environment outside the cloud, allowing the Agent to read the context as needed.
This idea aligns with the "decoupling the brain from the hands" proposed by Anthropic, also keeping the harness stateless, storing session logs outside the harness, and accessing the execution environment on demand through a unified interface. The difference lies in the scenario. That article describes managed services, mainly discussing on-demand created sandboxes and resources within customer VPCs; here, the first connection is to the user's daily use, possibly intermittently online personal machines, which have uncommitted modifications and local credentials. Therefore, this design supports BYOM (Bring Your Own Machine), allowing users' daily development machines or personal computers to connect to the cloud Agent, and also supports connecting to cloud-hosted machines or on-demand created computing environments.
As a result, an Agent is no longer limited to a single machine but can switch between different execution devices, choosing environments to execute commands and obtain context within those environments based on task needs. It can even support intermittently online devices, for example, automatically triggering and completing tasks that need to be executed on a user's personal device once that device comes back online. The figure below illustrates the structure after the separation of computation, persistent state, and various execution environments into two layers:
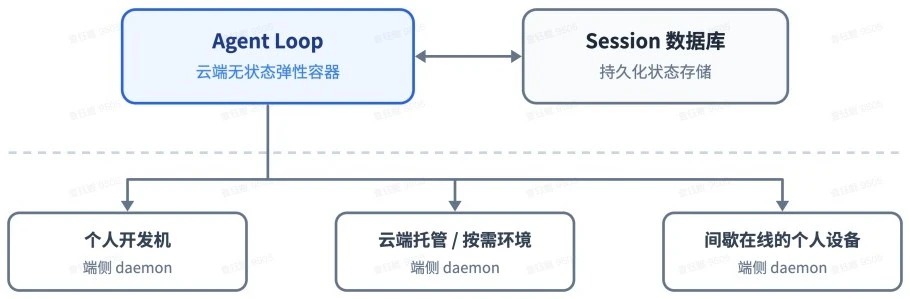
Separation of storage and computation and decoupling of execution environments: Agent Loop and persistent state are separated in the cloud and accessed on demand through an edge-side daemon for various execution environments.
6. Watchdog
To achieve persistent online status, in addition to the separation of storage and computation mentioned in Section 5, the system must also be able to automatically recover from anomalies during long-term operation. It is difficult for a distributed system to ensure long-term reliable operation solely based on the internal logic of the main system; an independent external control loop, known as the Control Loop, needs to be introduced outside the main system.
At the same time, in the Agent system, relying solely on traditional process survival detection or monitoring scripts is insufficient, as many anomalies do not involve process crashes but rather the model getting stuck in ineffective loops or deviating from its goals during execution. Therefore, a long-running Agent system needs to monitor not only the survival of the infrastructure but also the progress of the tasks themselves.
We configured an independent Watchdog Session outside the main system, driven by timed messages, forming an external Control Loop. The Watchdog handles basic infrastructure failures such as interface errors and state recovery failures, and it also assesses whether each Worker is making substantial progress and whether the direction is deviating from the overall goal. It intervenes promptly to fix issues when anomalies are detected and continuously reviews external sporadic failures until normalcy is restored.
Since the Watchdog itself is also an Agent Session with complete tool capabilities, maintainers can inquire about failure reasons in natural language and can have it online to correct the behavior of the main system, such as adding or deleting prompts and adjusting triggering rules.
7. Preliminary Experiments
To evaluate the core scheduling and routing design discussed earlier, we conducted preliminary experiments from two perspectives: first, comparing the dual-layer architecture, subscription direct access, and single Session solutions through end-to-end experiments (Section 7.1), and then separately testing the batch processing of the Router layer (Section 7.2). Since the experiments were based on synthetic loads and simplified environments, some settings could be more rigorous; the following results are only for preliminary reference.
7.1 Ablation Experiment
We simultaneously drove four end-to-end solutions using group chat and GitHub CI message streams: each experiment included approximately 300 messages, of which about 20 were work requests, while the rest were casual chats, follow-ups, stop commands, and CI messages. The coding work was replaced with a tool that only consumed time, so the experiment measured the system's scheduling and collaboration capabilities rather than the execution capabilities of a single task. Each solution was run 5 times.
The four solutions compared included Super-agent, Super-agent without direct access, and two single Session + Subagent tools under different prompt configurations.
The neutral prompt was written as "Use a subagent for a piece of work when appropriate…"
The prompt prioritizing delegation was written as "Every message of the chat reaches you, so work you run yourself keeps stopping for new messages. Prefer handing each piece of work to a subagent of its own, and do only small things yourself…"
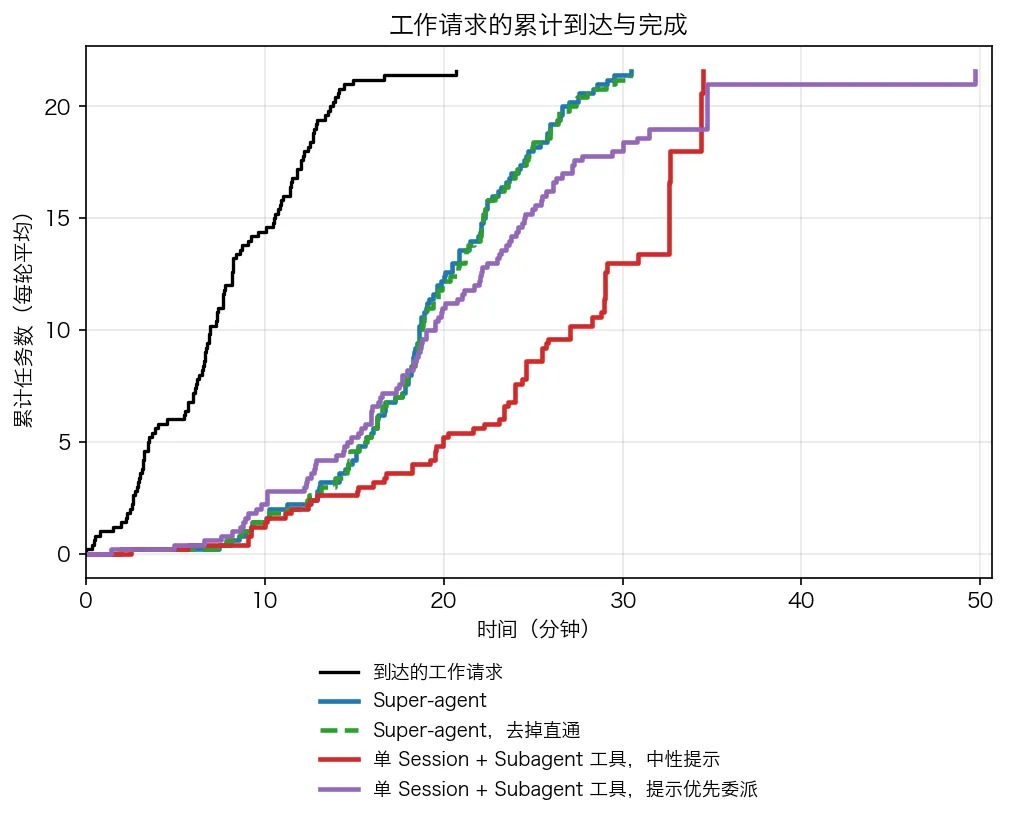
Cumulative arrival curve of work requests and cumulative completion curve of the four solutions (average of 5 experimental runs; message intervals and work durations scaled down by 1/4, model invocation times are real values)
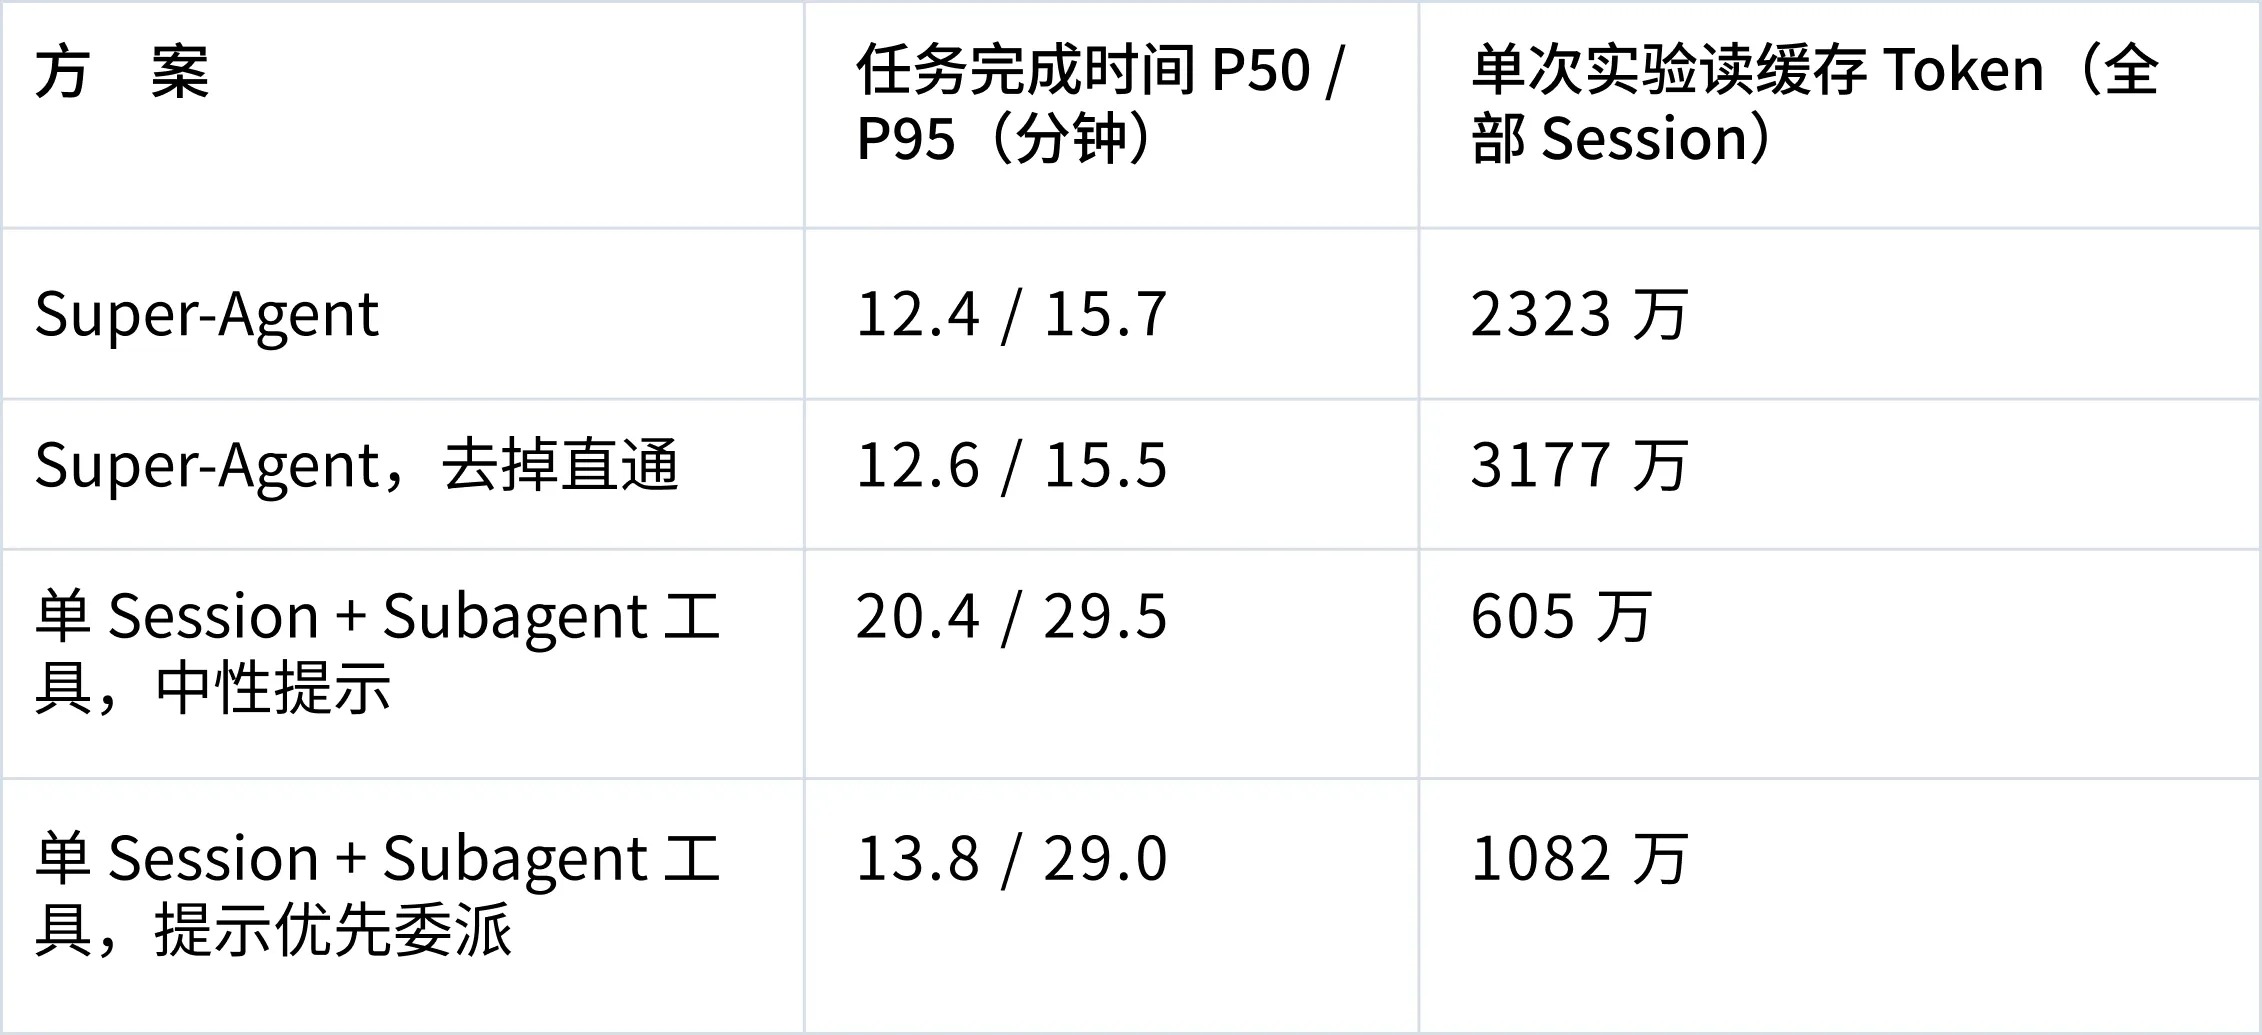
Each solution was run 5 times; task completion time refers to the time taken from work request to result message.
In terms of task completion time, the p50 and p95 of the Super-agent were 12.4 minutes and 15.7 minutes, respectively, significantly better than the single Session with Subagent tools. The reason is that the single Session with Subagent is greatly influenced by the prompts in the experimental scenario, and the main Session often decides to execute tasks directly, leading to longer total completion times and unstable performance. Under the neutral prompt, the model did not call the Subagent at all in 5 runs, with all work being done in the main Session and constantly interrupted by new messages, resulting in a p95 of 29.5 minutes; after changing to the prompt prioritizing delegation, the model delegated in 4 out of 5 runs, reducing completion time but still overall slower than the Super-agent, with the remaining run where it judged the work to be "very small" and chose to execute it itself, forming the long purple tail in the graph. Compared to relying on prompt engineering and model on-the-spot judgment for division of labor in a single Session, the dual-layer architecture alleviates this issue at the system level by allowing the Router not to directly execute specific work, and Workers only receive messages from the subscribed Thread.
In terms of system overhead, since multiple independent sessions were maintained, the read cache token of the Super-agent's single experiment was higher than that of the single Session, trading more token consumption for shorter and more stable completion times. After removing the direct access mechanism within the Super-agent, the task completion time was essentially the same as the full version, but the decisions the Router had to make in a single experiment increased by about 30%, with total read cache tokens increasing from 23.23 million to 31.77 million, an increase of about 37%. This indicates that under the experimental load, the direct access mechanism does not improve task completion quality and speed but saves considerable tokens and inference overhead for the Router Session.
7.2 Batch Processing of the Router Layer
To verify the throughput limit and batch processing mechanism of a single resident Router Session discussed in Section 2.1, we conducted stress tests specifically on the Router layer: allowing the Router to call real models while Workers used Mock models, and gradually increasing the arrival rate of Triggers needing decisions from about 1 per minute to about 40 per minute, observing the average batch size, single request time, and inference time allocated per decision.
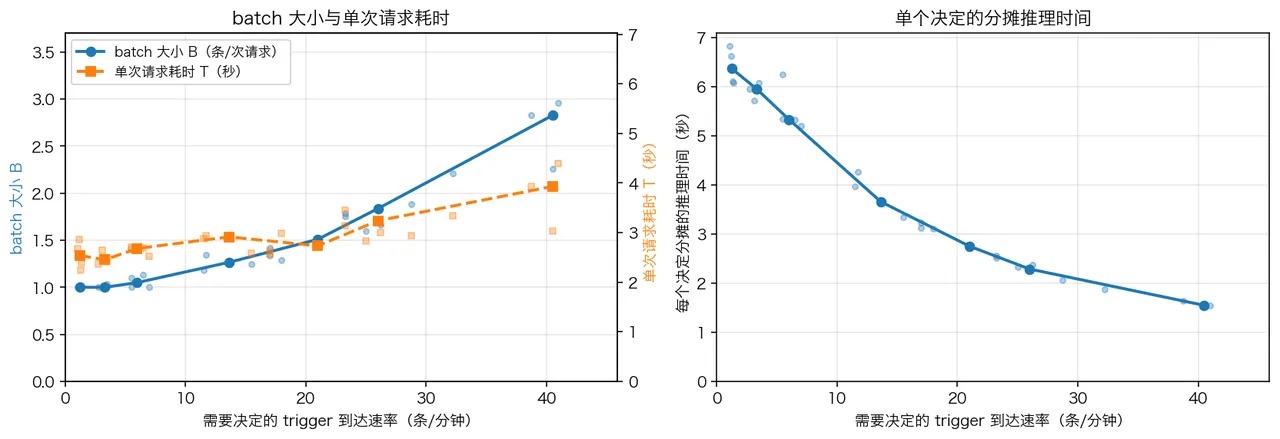
Batch size, single request time, and inference time per decision of the Router Session under different Trigger arrival rates
8. Open Questions
The five modules introduced in Sections 2 to 6 form the basic architecture supporting the operation of the Super-agent, and the experiments in Section 7 also validated the effectiveness of the core scheduling and routing mechanisms under multi-task concurrency. The reason this system can operate with relatively low complexity is largely due to a series of engineering and scenario simplifications made at the current stage. Beyond the applicable range of these simplifications, there are still some issues to be resolved regarding the expansion of the dual-layer architecture (Section 8.1), human-machine collaboration after leaving the Session (Section 8.2), context boundaries and A2A (Section 8.3), as well as security and privacy (Section 8.4).
8.1 How to Expand the Dual-Layer Architecture
The previous text covered most of our daily tasks with a simplified combination of "single resident Router Session + subscription direct access + no direct communication between Workers" at a relatively low engineering cost. However, when the task scale increases and coupling rises, exceeding the capacity of a single Router Session, there is no definitive conclusion on the specific internal structure of the layers, when the Router layer needs to be horizontally split, how to define granularity, and when to introduce direct communication between Workers at the same layer, as well as what kind of collaboration topology to adopt, still needs to be tested in more scenarios. At the same time, the co-design of the system and model is also a direction worth exploring, with specialized training for tasks such as event discrimination, batch dispatch, and context recall in the Router layer potentially further enhancing the throughput and decision-making performance of the Router layer.
Meanwhile, the resident Router layer in the previous text, combined with reference graph-based chain recall, primarily addresses the on-demand retrieval of recent tasks and session history. When the operational cycle extends to cross-month or even longer time spans, long-term memory becomes the main bottleneck limiting scalability.
8.2 How to Collaborate with Agents After Leaving the Session
The previous text concealed the underlying multi-session management from users through the dual-layer architecture, making Sessions no longer the primary concern of product design; however, when the underlying execution sessions no longer directly correspond to the sessions on the user interface, how to present tasks to users and provide natural interaction and project management forms becomes a new issue. We believe that chat window-centered interaction is to some extent a result of path dependence. Interactions may occur more in domain-specific interfaces, such as allowing the Super-agent to work directly within GitHub Issues and Pull Requests as in this example; Sessions can also be retained in the interface due to user habits, but a single session seen by the user may not correspond to just one Session at the underlying level.
At the same time, the previous text mainly discussed human interaction during the task initiation and result acceptance phases; however, during the transitional period of rapid evolution of model capabilities, many tasks still require human participation midway. How to balance users' gradual intervention in key details with the efficiency of autonomous advancement in product design, such as allowing users to intervene, take over, or collaborate in real-time with the Agent during the background execution process, is also worth exploring.
Overall, the project management and interaction forms required by users are closely related to specific work domains and personal styles, and the final form is likely to be highly customized; since DeepSeek Harness adopts an open architecture design, it is also more conducive to supporting such customization.
8.3 How to Define Context Boundaries and Conduct A2A Collaboration
The previous discussion has always focused on the design within a single Super-agent instance, assuming that all information within its service scope is aggregated in the same global context. However, when the usage scope expands from individuals or small teams to larger organizations, the organization is essentially delineating the boundaries of context sharing and isolation when deciding how to equip Super-agents. Areas that need to share context share the same instance, while areas that need isolation are independently equipped.
Looking further, once there are multiple isolated instances within or between organizations, such as individual assistants for each member and a shared Super-agent for the team, cross-boundary collaboration becomes communication between Agents (A2A, not referring to any specific protocol). Under the premise that the underlying context is not shared and each represents different permission boundaries, how to achieve secure and reliable A2A communication and collaboration still requires further exploration.
8.4 How to Ensure Security and Privacy
The event-driven design in Section 3 allows Agents to be driven by a broader environment, but it also increases the risk of encountering untrusted inputs. If security and privacy issues cannot be effectively resolved, then the Super-agent can only operate within a very small and trusted scope.
For example, Section 5 deploys the Agent Loop in the cloud and installs lightweight daemons on various execution devices, which assumes a trusted relationship between the cloud and edge environments. However, when the cloud's Agent Loop continuously connects to external environmental events, while private code, sensitive data, and local credentials exist on the edge devices, this cross-device connection introduces significant security and privacy risks. If the cloud's Agent Loop encounters server-side intrusion or prompt injection and is compromised, all connected edge devices face the potential risk of being controlled.
Moreover, even if the cloud is not compromised, as long as the credentials in the edge environment can enter the model's context, there is still a risk of credential leakage during normal execution; therefore, corresponding mechanisms need to be designed to allow Agents to use credentials without directly accessing them. If this architecture is to move towards broader applications, it needs to address the aforementioned security and privacy issues while being able to recall context from diverse environments.
9. Conclusion
Looking back at the entire design, we have not proposed a completely new theory, but rather applied classic engineering ideas from computer systems to the construction of Agent systems. The specific implementation methods will evolve with technological development, but we believe the underlying system design concepts have long-term reference value. Currently, the internal Super-agent instance built on this concept and DeepSeek Harness is continuously running, participating daily in problem reproduction and resolution, code review responses, and iterations of DeepSeek Harness itself.
As mentioned at the beginning, as large models require less human intervention to perform single tasks, the bottleneck limiting further productivity enhancement is shifting towards human attention. Through a dual-layer architecture, event-driven design, asynchronous multi-channel interaction, separation of storage and computation, and external watchdogs, the system takes over cumbersome session management and context synchronization at the foundational level, allowing humans to move from specific execution details to higher-level decision-making and acceptance.
In this form, the Agent is no longer just a passive dialogue window waiting for instructions, but evolves into a continuously online autonomous collaborator in the digital environment: for individuals, it can be a personal assistant assisting in handling daily affairs across devices; for teams, it integrates into the R&D workflow, undertaking and advancing specific tasks. We believe that with the joint evolution of model capabilities and underlying system architecture, this more autonomous working method is expected to become the norm in human-machine collaboration.
Some of the designs in this article have been implemented in the dsh-superagent-prototype. This plugin is merely a prototype provided to validate the technical route and is not an official product of DeepSeek.
Author & Acknowledgements
This article originates from the collective practice of the DeepSeek Harness team. Yujia Qiao completed the system implementation and writing of this article, while Huanqi Cao, Zui Chen, Xieting Chu, Tianyi Cui, Shiyuan Feng, Yudong Han, Kexin Liu, Shichun Liu, Gesi Luo, Yifan Shi, Tongrui Xiong, C.C. Yu, Ziya Zhang, F. Zhou, and others participated in review discussions and provided feedback. The implementation of the system and the formation of the article could not have been achieved without the team's daily communication and accumulation.
 Risk warning
 Risk warning