U.S. stocks suffered a bloodbath overnight, losing 2.8 trillion! Top Silicon Valley VC reveals: 90% of spending on open-source models flows to China
 Core Viewpoint


 As the U.S. stock market evaporated $2.8 trillion overnight, a spending report disclosed by Silicon Valley VCs is even more noteworthy: approximately 89% of corporate open-source model spending flows to Chinese models, with Kimi accounting for 61%; meanwhile, funds are accelerating towards more expensive flagship models.
Source: Xinzhiyuan Report
In the early hours of today, U.S. stocks were bloodied.
The Nasdaq index plummeted by 5.52%, marking the largest single-day drop since April 2025, officially entering a technical correction zone. The Philadelphia Semiconductor Index crashed by 12.3%, the worst day since the pandemic crash in March 2020.
NVIDIA dropped by 9.26%, evaporating nearly $450 billion in market value in one day; AMD fell by 17%, SanDisk by 22%, and Broadcom by 10%.
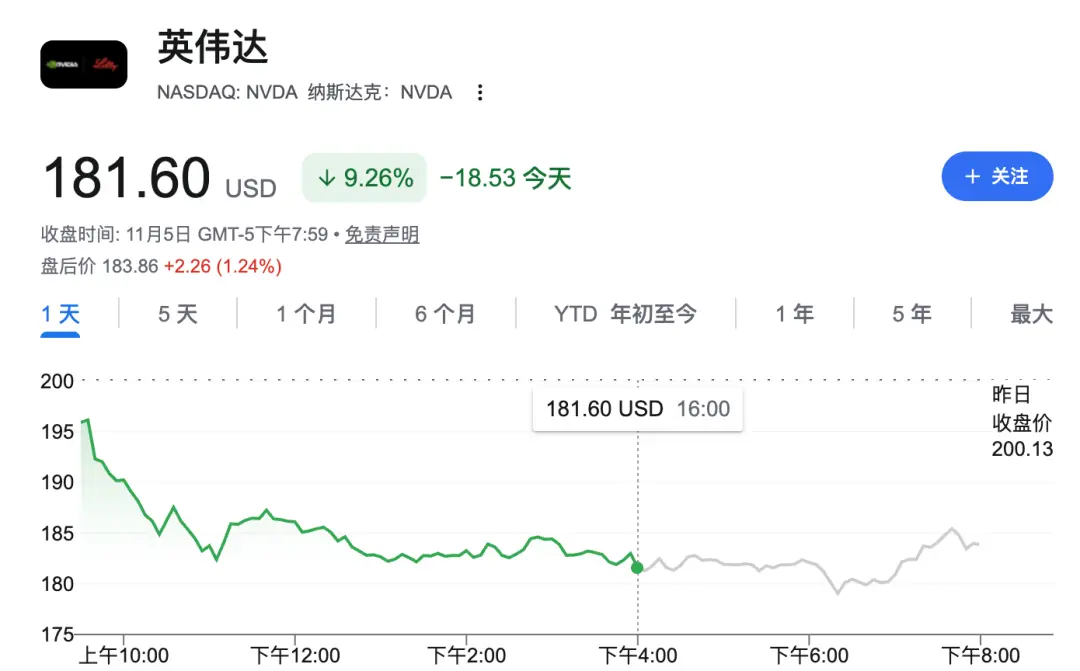
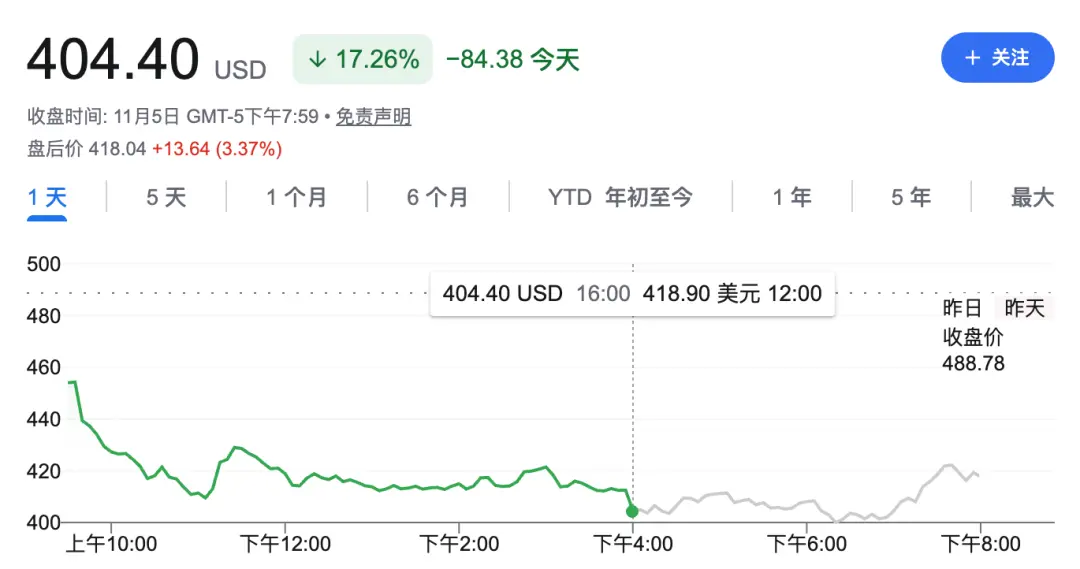
From chips, servers, optical modules to power suppliers for data centers, almost no corner of the entire AI infrastructure industry chain was spared.
Media estimates suggest that U.S. stocks evaporated about $2.8 trillion in one day!
Setting aside the election impact, a deeper layer of doubt about whether the massive AI capital expenditures "can actually pay off" finally erupted.
But just two days ago, on November 3, Menlo Ventures, a 50-year-old venture capital firm in Silicon Valley and an early investor in Anthropic, released the "2026 Corporate AI Status Report," which presented numbers that went in completely the opposite direction of the stock market:
Corporate AI deployment spending is projected to soar from $33 billion to $177 billion by 2026, a staggering increase of 5.4 times in just one year. Three years ago, this figure was only $1.7 billion, a 100-fold increase in three years.
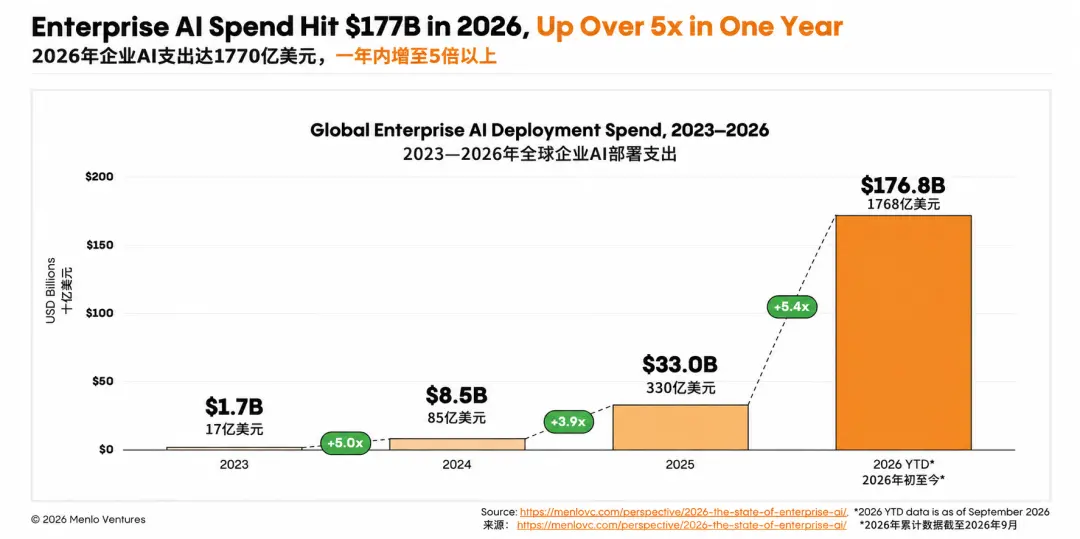
On one side, $2.8 trillion has vanished into thin air, while on the other side, $177 billion in real money is being poured in.
The contrast is absurd. Wall Street is skeptical about whether supply-side capital expenditures can pay off, while CTOs on the demand side are increasing orders to the point of losing control of their budgets.
This report also hides two more intriguing clues:
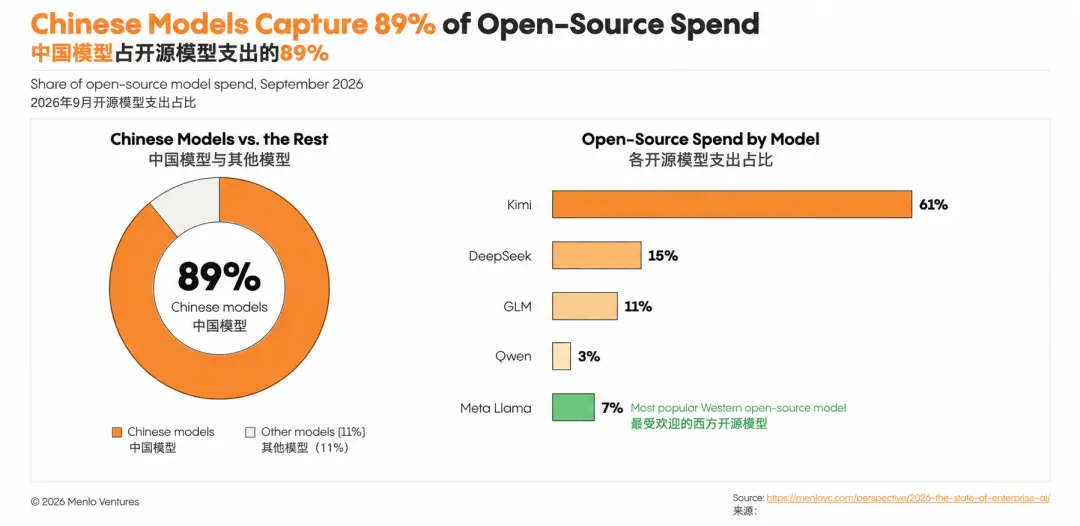
Chinese models accounted for 89% of corporate open-source model spending, with Kimi taking 61%; at the same time, corporate funds are accelerating towards more expensive flagship models, with the spending share on cutting-edge models rising from 35% to 63%.
Putting these two things together reveals the real spectacle.
Chinese Models Are Dominating Corporate Accounts in the U.S.
In corporate open-source model spending, the Chinese contingent overwhelmingly occupies the top four positions: Kimi 61%, DeepSeek 15%, GLM 11%, Qwen 3%, totaling 89%. Meta's Llama, the most prominent open-source contender from the Western world, only captured 7%.
In other words, when U.S. companies run open-source models in production environments, nine out of ten times, the underlying technology comes from China.
But what's even more interesting is that Chinese models are no longer just "cheap alternatives" — they are starting to "grow" into others' products.
Just yesterday, on November 5, Thinking Machines Lab released a new model, Inkling 2 Small. This company needs no introduction: founded by former OpenAI CTO Mira Murati, it raised $2 billion in its seed round, with a recent valuation of $40 billion, making it one of the most prestigious labs in Silicon Valley.
The model itself is impressive: 594 billion total parameters, 17 billion activated MoE, with an Artificial Analysis intelligence index score of 31.
But that's not the main point. The key lies in an inconspicuous corner of the technical blog —
As pre-training progresses, most of the data fed to the model is not scraped from the internet but generated by running several earlier models first. The first one named is Kimi K3 from Dark Moon.
What does this mean? It means Kimi has acted as a teacher for Silicon Valley's star labs.
The premise of being a teacher is that the answers you provide are worth copying. A year ago, this role was primarily held by GPT and Claude.
Being a teacher is just one application. Kimi K3 is also serving as a foundation for U.S. companies.
In August of this year, legal AI unicorn Harvey — valued at over $10 billion, with OpenAI as one of its shareholders — released its first model, Tenet.
Who is the foundation? It's not OpenAI's GPT, but Kimi K3.
Harvey used about 150 NVIDIA B300s and spent two months training on Kimi K3 for legal tasks.
As a result, Tenet nearly doubled the number of tasks completed on its own legal Agent benchmark, competing effectively with flagship models from Anthropic, OpenAI, and Google on several complex legal tasks.
The model-building Thinking Machines treats it as a teacher, while the application-focused Harvey uses it as a foundation. From the lab to the application layer, Kimi has squeezed in.
For these companies, open weights mean they have a knife they can sharpen themselves, rather than just a cheap knife.
Thus, Chinese models have entered the production chain of overseas top applications — from being called upon to being treated as teachers and foundations.
Moreover, this momentum is accelerating.
The Kimi K3.1 Pro, just released on October 23, reported a Terminal-Bench 4.0 score of 65.7%; shortly after, on November 5, it landed on Microsoft Foundry —
This is the first open-source weight model to adopt a "revenue-sharing" model on Microsoft Cloud. Simply put, every time a company calls Kimi on Microsoft Azure, Dark Moon shares the revenue.
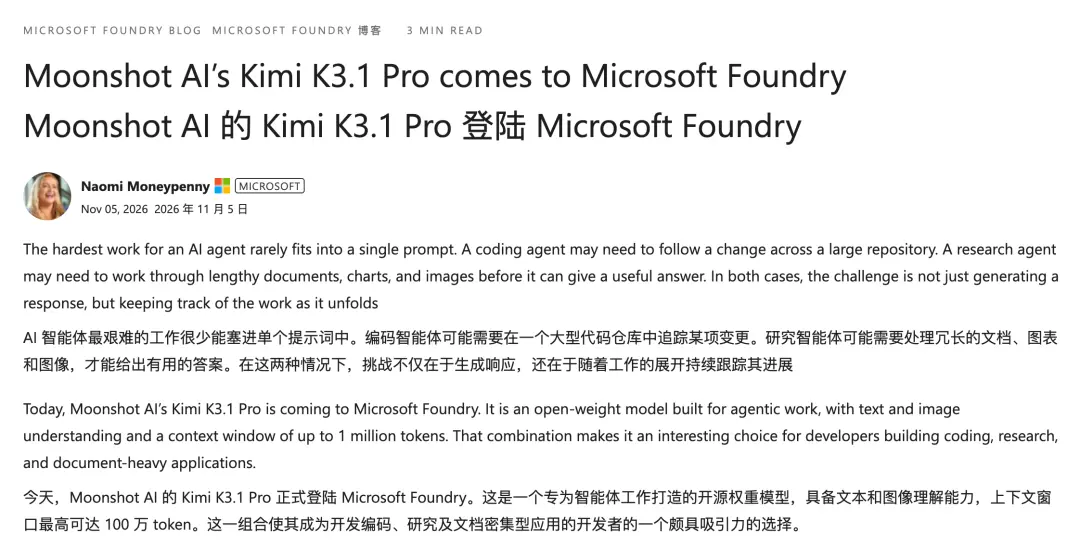
Before Microsoft, Kimi had already been launched on Amazon AWS. Microsoft and Amazon, the two largest clouds in the world, have successively issued "tickets" for Chinese open-source models.
Another Account: Usage Doubles, But Money Doesn't Follow
With such strong performance from Chinese open-source models, should closed-source models be worried?
The story is far from that simple.
If we only look at usage, the momentum for open-source is indeed strong: token share rose from 11% to 19%, and monthly processing volume skyrocketed by 22.5 times, reaching about 29 trillion tokens.
But what about the money? The spending share actually dropped from 6% to 4%.
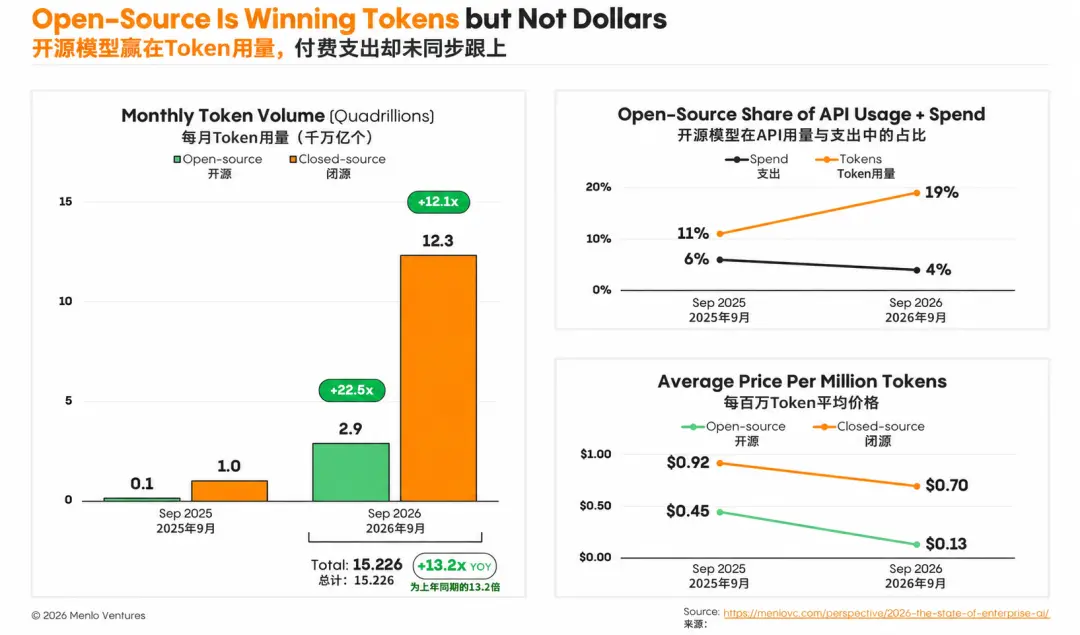
The reason is quite painful: over the past year, the open-source camp has mostly been focused on the same thing — creating smaller, faster, and cheaper "flash" models, fiercely competing on price.
In one year, the average price of open-source tokens has dropped by 3.3 times, now costing only $0.13 per million tokens; closed-source models average $0.70, over five times more expensive.
The result of the price war is that while the workload has doubled, the revenue has actually decreased — the entire increment has been eaten away by price cuts.
The open-source Flash models won the shouting match, while flagship models won the wallets.
Corporate budgets do not distinguish between open-source and closed-source; they only recognize who can get the job done. However, in the open-source camp, there are only a handful of players that qualify as flagships.
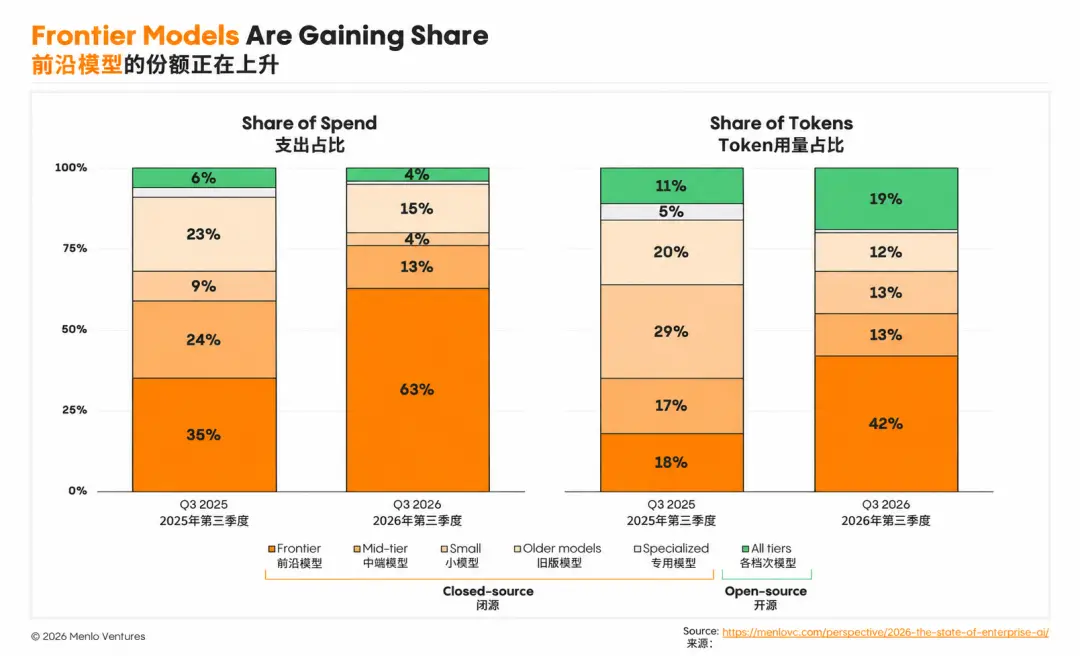
This is the most counterintuitive finding of the entire report: the spending share on cutting-edge flagship models soared from 35% to 63%, while the token share doubled from 18% to 42%.
Last year, the mainstream choices for enterprises were Claude Sonnet 4.5 (at $3 per million input tokens) and GPT-5 ($1.25); this year, they have switched to Claude Opus 5.5 ($4) and GPT-6 Astra ($10). Prices have multiplied several times, yet users have not fled but instead flocked in.
Where has the money flowed? Anthropic's share rose from 40% to 55%, OpenAI's from 27% to 31%, with the two companies capturing 86% of corporate LLM API spending. Google's share dropped from 21% to 9%, falling behind.
Meanwhile, Kimi K3, DeepSeek V4, GLM-5.3, and other performers that are already approaching flagship capabilities collectively account for less than 5%. The capability is there, but companies have not yet dared to entrust their core operations to them.
The most unfortunate are those stuck in the middle: small closed-source models have seen prices drop by over 80%, yet their token share still fell from 29% to 13%. The flagship models above are taking away complex tasks, while open-source models are snatching simple jobs, squeezing from both ends, leaving them in a tough spot.
So why are companies willing to spend more money?
Imagine this: having AI fix an online issue, reading code, checking logs, pinpointing problems, modifying files, running tests. Cheap models go off track every few steps, requiring repeated explanations, checks, and rework, ultimately leading you to step in yourself. The token bill may be saved, but the entire afternoon of the engineer is spent.
Thus, the account that enterprises keep in mind is not about how many dollars per million tokens, but rather how much it costs to complete the task from start to finish. The model invocation fee is just a small part; the real money is burned in monitoring, waiting, and modifying.
Cheap is certainly good, but it has to come with a premise — the work must actually get done.
But can open-source not handle big tasks?
Take Kimi K3.1 Pro as an example: with a 2.8 trillion parameter MoE architecture, supporting a context window of 1 million tokens, it scored 65.7% on Terminal-Bench 4.0, surpassing GPT-6 Astra.
It achieved a score of 64.4 on the financial research benchmark OfficeQA Pro v2, ranking first globally. The hallucination error rate was reduced from the previous generation's 23.4% to 6.85%.
This is no longer at the level of "just usable"; it is at the level of competing with closed-source flagships.
The shortcoming of open-source has never been intelligence, but rather the degree of trust enterprises have in it — compliance, after-sales service, long-term roadmap; these "scores outside the exam room" are the final hurdle.
Ultimately, the sharp drop in U.S. stocks today and the data in this report tell two sides of the same story.
Wall Street is focused on the supply side: massive capital expenditures, data center approvals, power costs, all hanging like swords over their heads.
Meanwhile, the Menlo Ventures report focuses on the demand side: for every dollar spent training a model, companies spend $1.70 using it — downstream demand is providing a safety net for upstream investments.
At the beginning of the year, Wall Street was panicking over "AI eating SaaS." The results showed that 55% of new AI spending came from entirely new budgets, while only 9% was shifted from traditional software budgets to AI-native vendors.
AI is expanding the pie, not fighting over it.
Menlo Ventures, which compiled this report, had their partner Tim Tully say a straightforward truth:
Wall Street keeps asking whether AI can pay off, but what we see is that enterprise buyers are not holding back; instead, they are looking for ways to make AI do more work.
"We may still be underestimating this market."
Stock Prices Will Fall, Bills Don’t Lie
Looking back at the three contrasting groups hidden in this report:
Flagship vs Open Source. Flagship models accounted for 69% of deployment spending, and the first-mover advantage of frontier labs has been amplified in the Agent era.
But the report also made a profound statement—"The scarcity of capabilities will not last long."
Whenever open source catches up with flagship models on certain tasks, the original premium must be re-evaluated.
Closed-source flagship models do not have permanent premium rights.
Usage vs Revenue. Chinese open source has proven its capabilities with an 89% share, but between 19% token usage and 4% spending lies a commercialization challenge.
Being widely used is one hurdle; being able to consistently handle complex tasks and keep customers paying is the next.
The cases of Harvey and Thinking Machines provide one path—relying not on being cheap, but on becoming someone else's teacher and foundation; the revenue-sharing model of Microsoft and AWS offers another—cooperating with cloud giants, charging per usage.
Stock Prices vs Bills. The contrast between Wall Street and enterprises is not as contradictory as it seems.
Stock prices reflect expectations, while bills record reality. A daily evaporation of 2.8 trillion is expectations correcting, while a yearly increase of 5.4 times is reality accelerating. Both can be true at the same time.
But looking further, what this report reveals may not just be a business cycle—but a redistribution of industrial power.
Three years ago, AI was a toy in the lab; three years later, enterprises are spending $177 billion a year using AI, an amount that already matches one-third of the entire public cloud revenue.
The main workforce has also changed, with 80% of tokens being consumed by Agents themselves.
Who can build effective models, who trains the models, and who helps run the models—all the divisions of labor along the entire chain are being rewritten by China's open-source forces.
 Risk warning Risk warning